Migration guide
Move media from ImageEngine to FileSpin
Move to FileSpin with every original reconciled and a working delivery route. Start with a catalogue refresh: find the right original, review the change, prepare card and banner outputs, and verify delivery across the pages that use them.
There are two ways to run the move. Both start with an inventory and a representative sample before the full transfer.
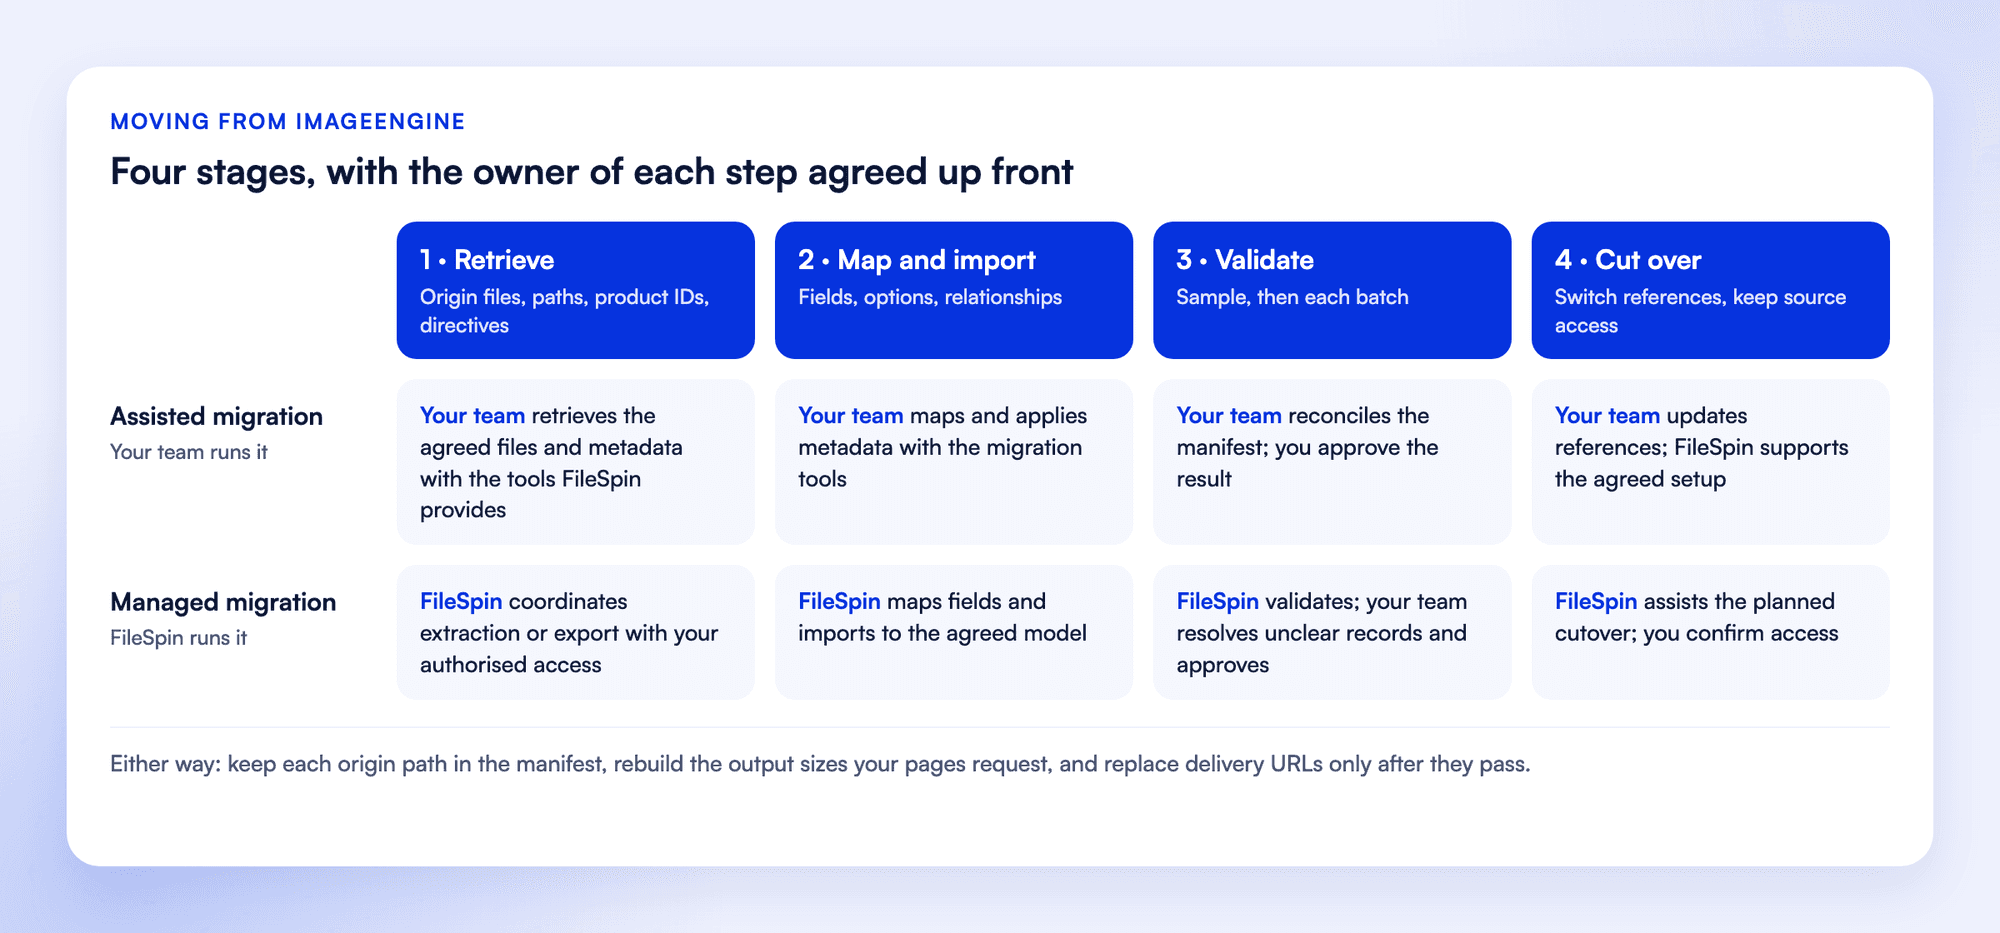
1. Retrieve the source files and records
ImageEngine reads your originals from your own origin, so the migration copies them straight from there: the web server, S3 bucket or Google Cloud Storage behind each delivery address. Business metadata comes from the CMS, PIM or database that holds it. The manifest records each delivery address, origin, object path, directives and origin access rule, and retained revisions come from your origin’s version history.
Retrieval uses an authorised source account, with credentials kept out of exports, screenshots and public URLs. Each completed inventory page and download is saved, so interrupted work resumes where it stopped, and expired download links are refreshed.
2. Create a manifest you can reconcile
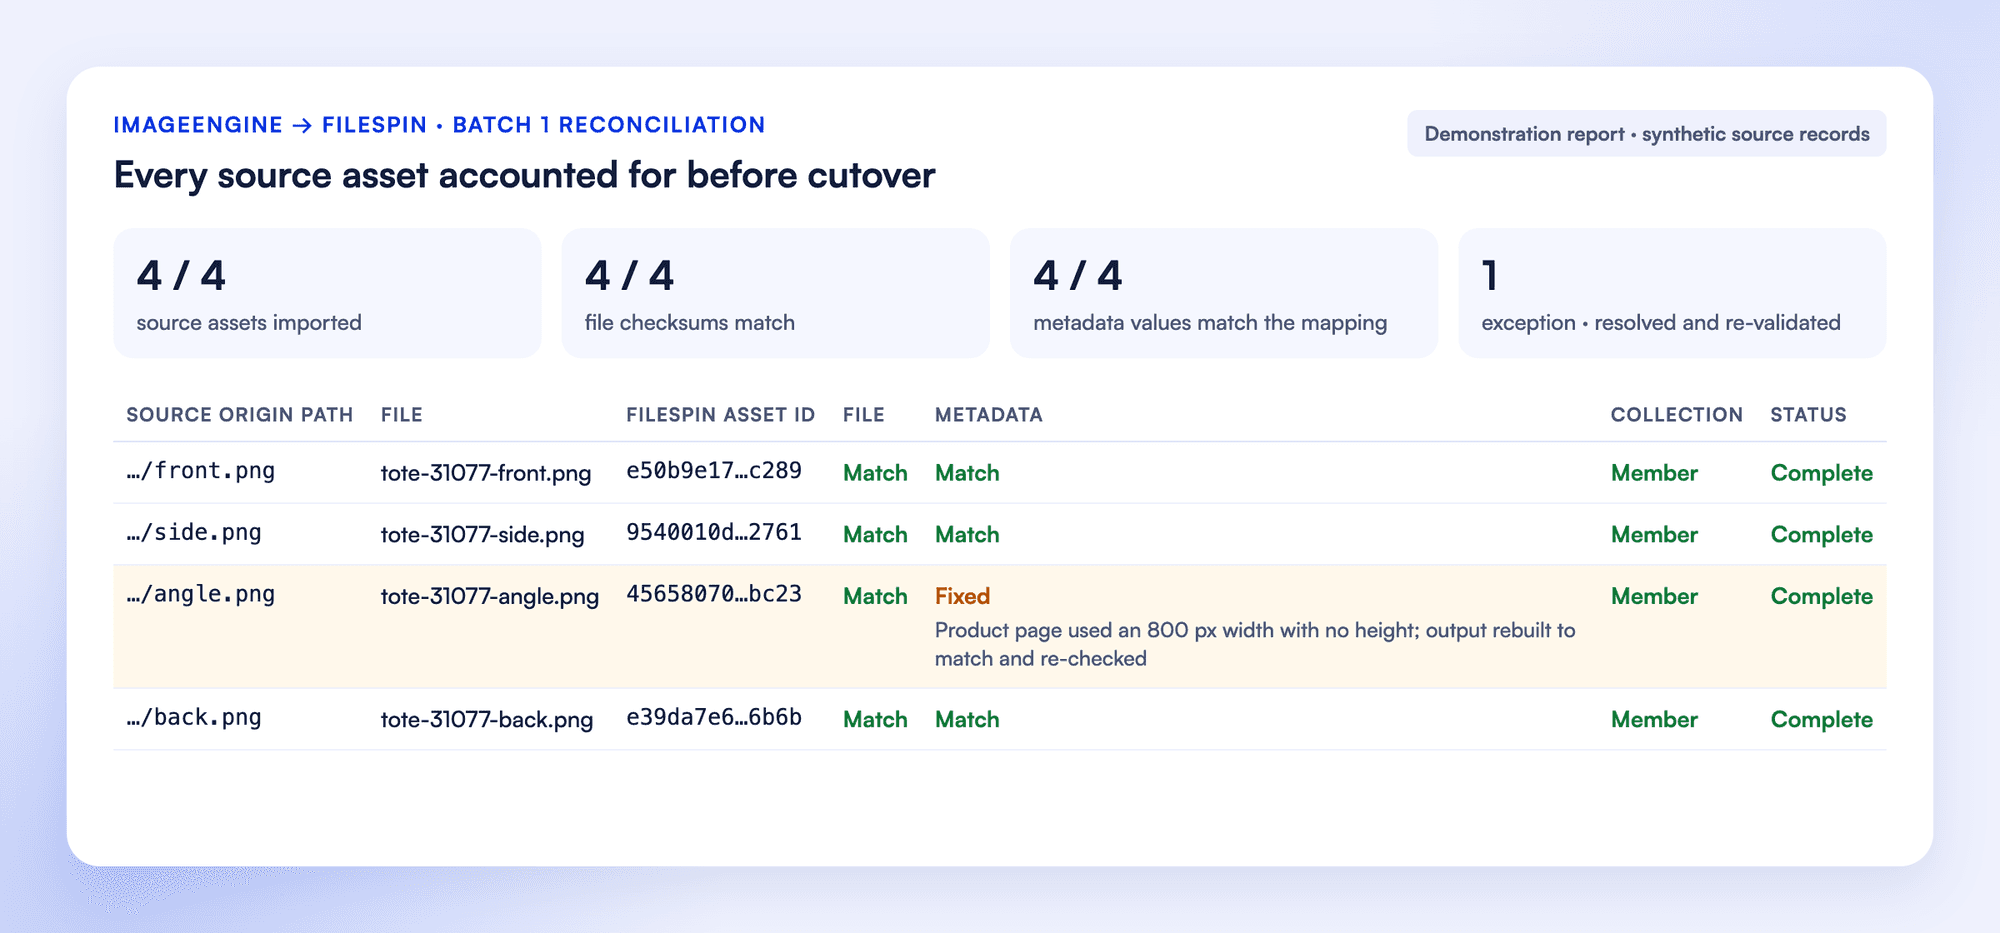
One record per source file or retained version: source system, asset ID, file or version ID, original name, source path, file type, bytes, a checksum recorded at download, tags, custom metadata, collection membership, rights information and source update time. The FileSpin asset ID and transfer status are added as work progresses.
Original files are kept separate from thumbnails and delivery renditions. Every exception, such as a missing original, a restricted download or an unsupported format, is listed with its resolution.
3. Map what moves and what gets rebuilt
Part of the library | What happens |
|---|---|
Originals | Authorised source files downloaded and reconciled against the manifest |
Metadata | Origin paths and product identifiers map to FileSpin assets and business fields. Your image outputs become FileSpin processing settings, with a source-path-to-FileSpin-ID manifest. |
Collections | Collections built from origin folder paths or your business data |
Versions | The revisions you keep, retrieved alongside the current files |
Access | Roles, private delivery and review workflows set up in FileSpin |
Delivery | Each ImageEngine directive is rebuilt as the matching FileSpin output in your image builders and responsive markup. Device sizes, crops, formats, quality and cache refresh are checked against current output before cutover. On ImageEngine Kube (self-hosted), the delivery hostname is yours and points at your Kube deployment, so your team switches it at cutover. |
History | Delivery analytics stay in ImageEngine; FileSpin records delivery and share analytics from cutover |
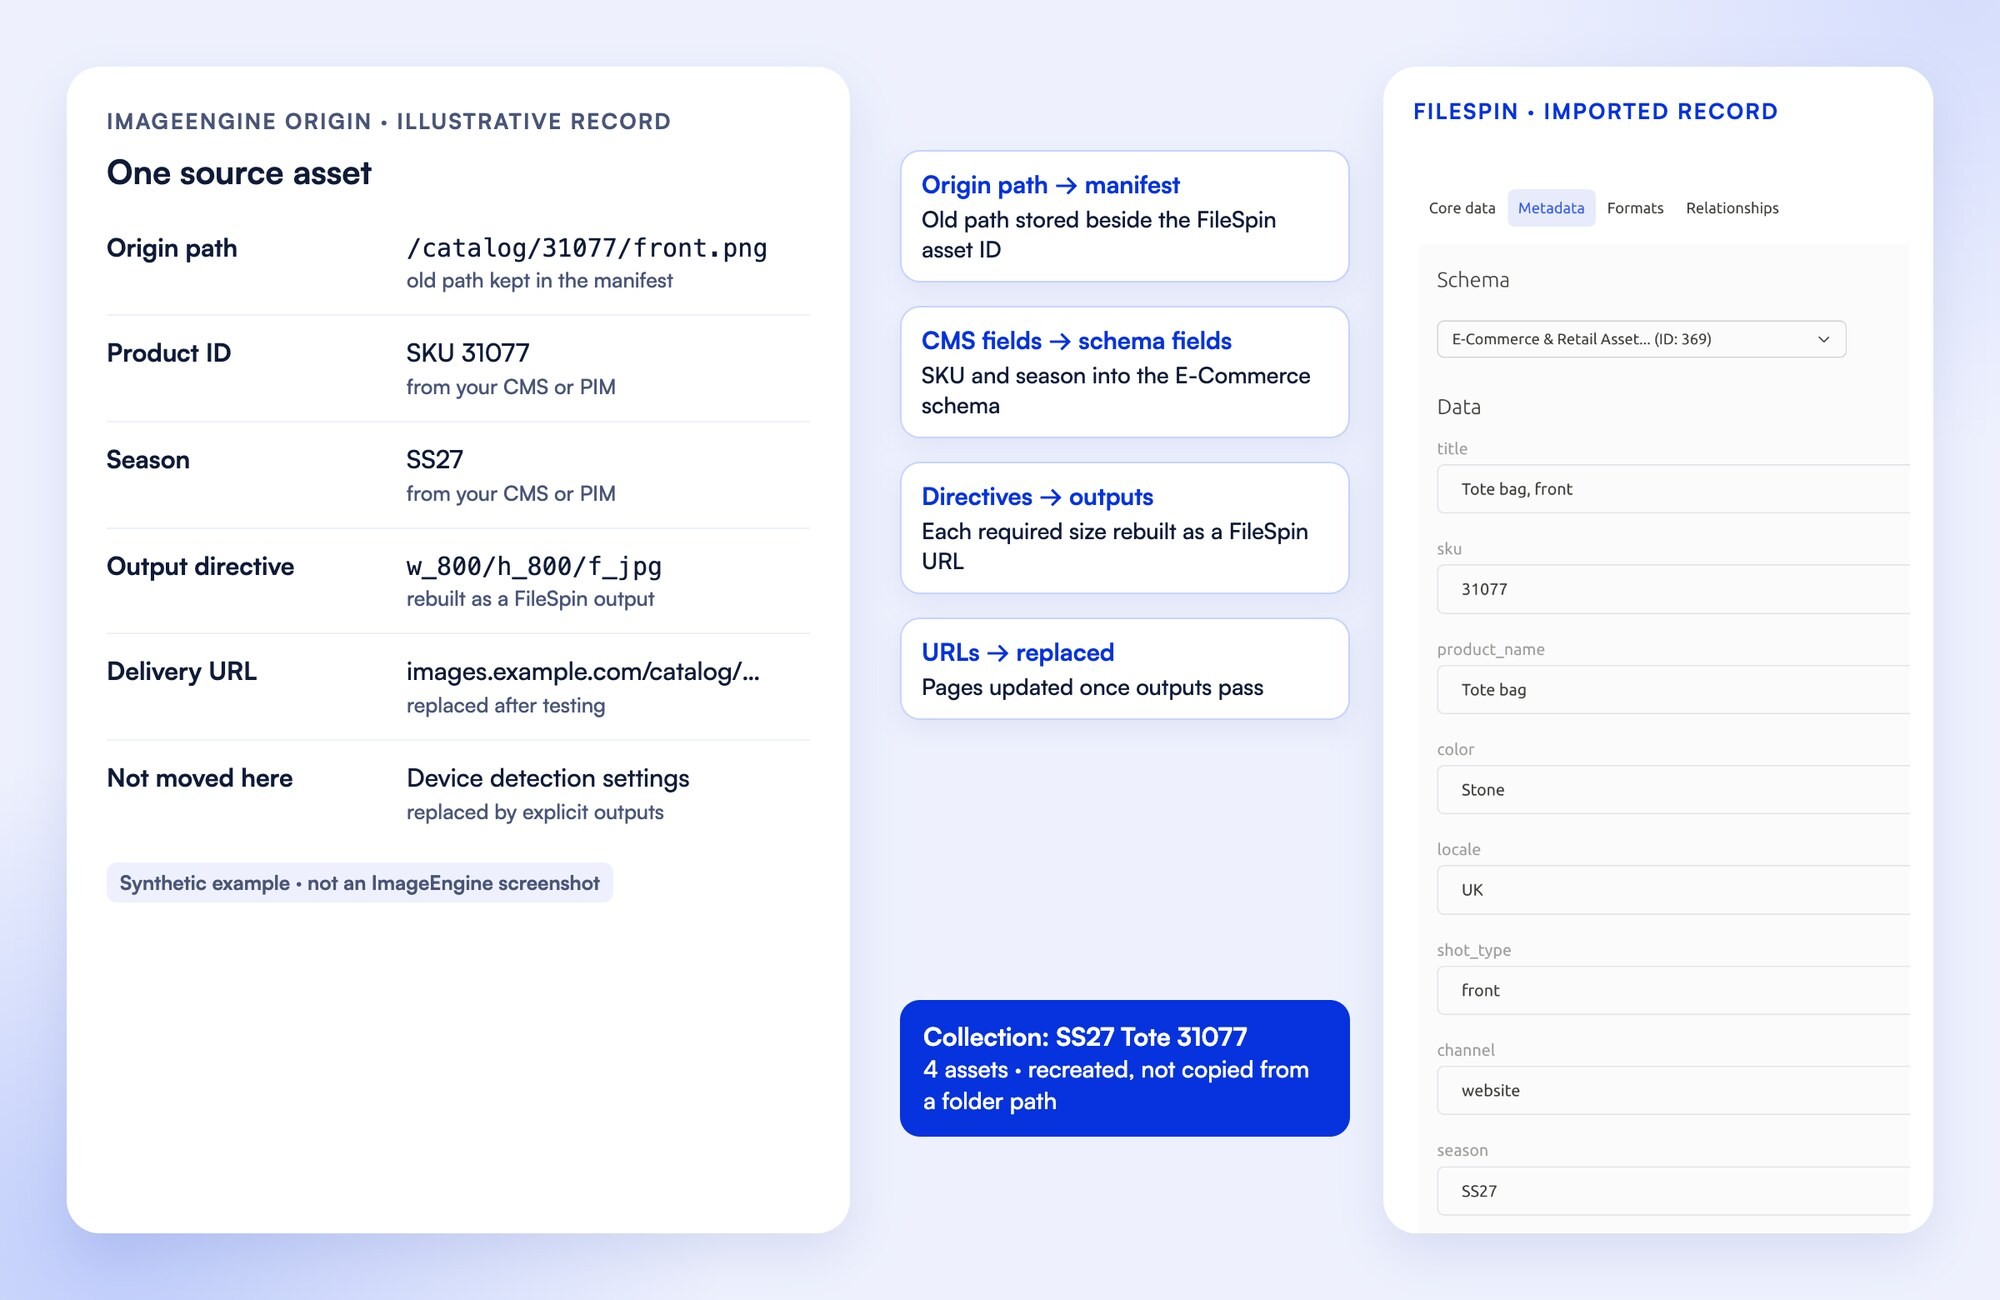
4. Import and check a sample
The sample includes several file types, a multi-value metadata field, an asset in more than one collection, a retained revision and restricted content. Files are loaded, FileSpin IDs recorded, mapped metadata applied and relationships rebuilt.
In an assisted migration, your team stages the retrieved files with the tools we provide and loads metadata through the mapping. In a managed migration, the FileSpin team carries out these steps.
The sample passes when:
- The correct file and intended version opens in FileSpin.
- Required fields, types and controlled values match the mapping.
- Collection membership counts match and related assets resolve.
- Version records and current files match the scope.
- An authorised user gets access and an unauthorised user is refused.
- A content owner finds the selected assets by business fields and completes a review.
- Real pages, players and feeds return the intended output, including after a replacement.
- A test campaign link and a share download appear in Delivery Insights and Share analytics.
- If agent work is included, its first run touches only the selected assets, stays within budget and reports its outcome.
- Every exception is listed and resolved before the full run.
ImageEngine migration questions
Do our ImageEngine URLs keep working?
Can we keep working in ImageEngine during the migration?
Do metadata and folders come across?
Do we need to run the migration ourselves?
5. Cut over
6. Sign off the result
- Every in-scope source file has a destination ID or an accepted exception.
- Required metadata, relationships, versions and access controls pass the agreed checks.
- Applications use the intended delivery route and updates appear correctly.
- The exception report, ownership map and recovery procedure are handed over.
Plan your ImageEngine migration with FileSpin. Tell us the size of your library, the history you need and the systems it feeds, and we’ll scope an assisted or managed migration with you.